Motif
Making ethical, microtonal AI audio tangible through a focused live experience
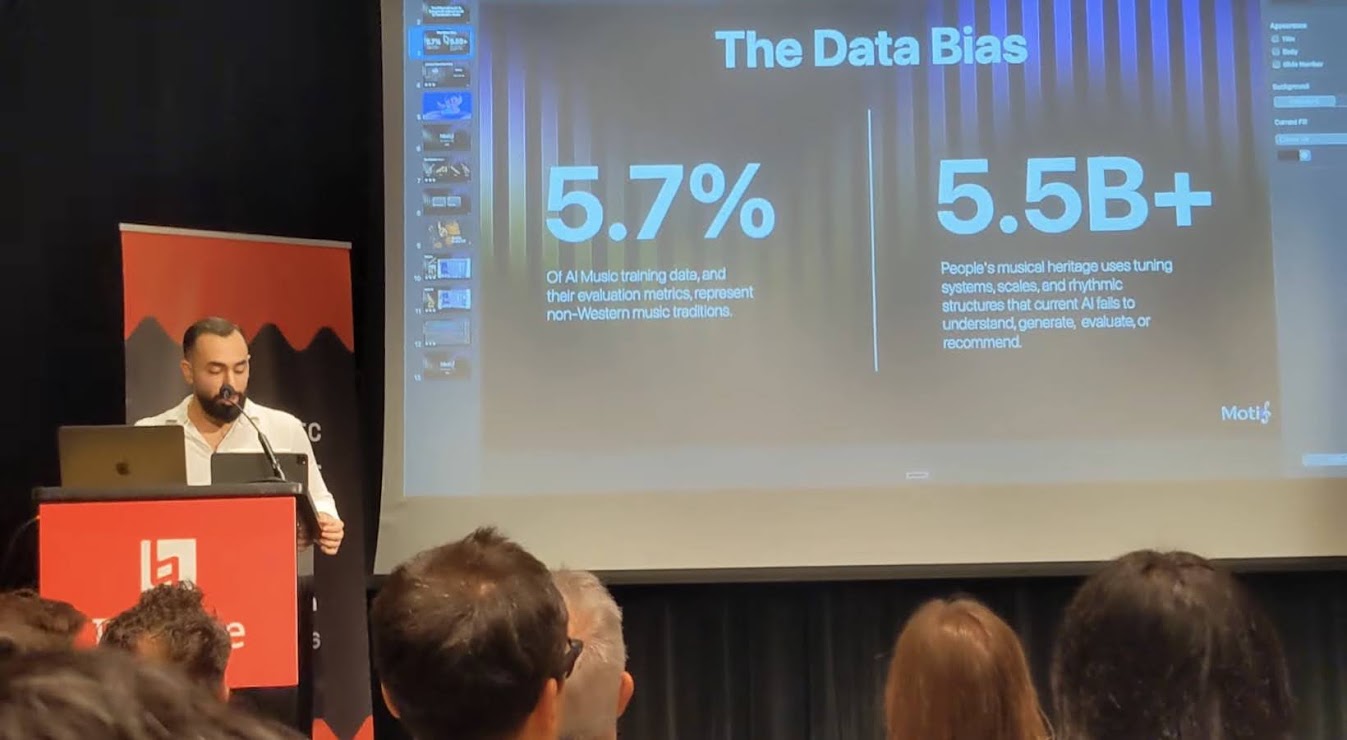
Motif explored what generative audio could become when trained to support musical traditions outside the Western twelve-tone framework. Most AI music systems are built around musical material rooted in that system, leaving other tonal traditions less represented. Our team approached the hackathon with the goal of demonstrating a model trained on ethically sourced material that could work with microtonal music and broaden what an AI-assisted music workflow could support.
The technical model was only part of the challenge. A trained model is difficult to communicate on a stage, particularly to an audience that may not already understand microtonality or the underlying technology. We needed to turn that research into an experience people could interact with, understand quickly, and ultimately hear for themselves.
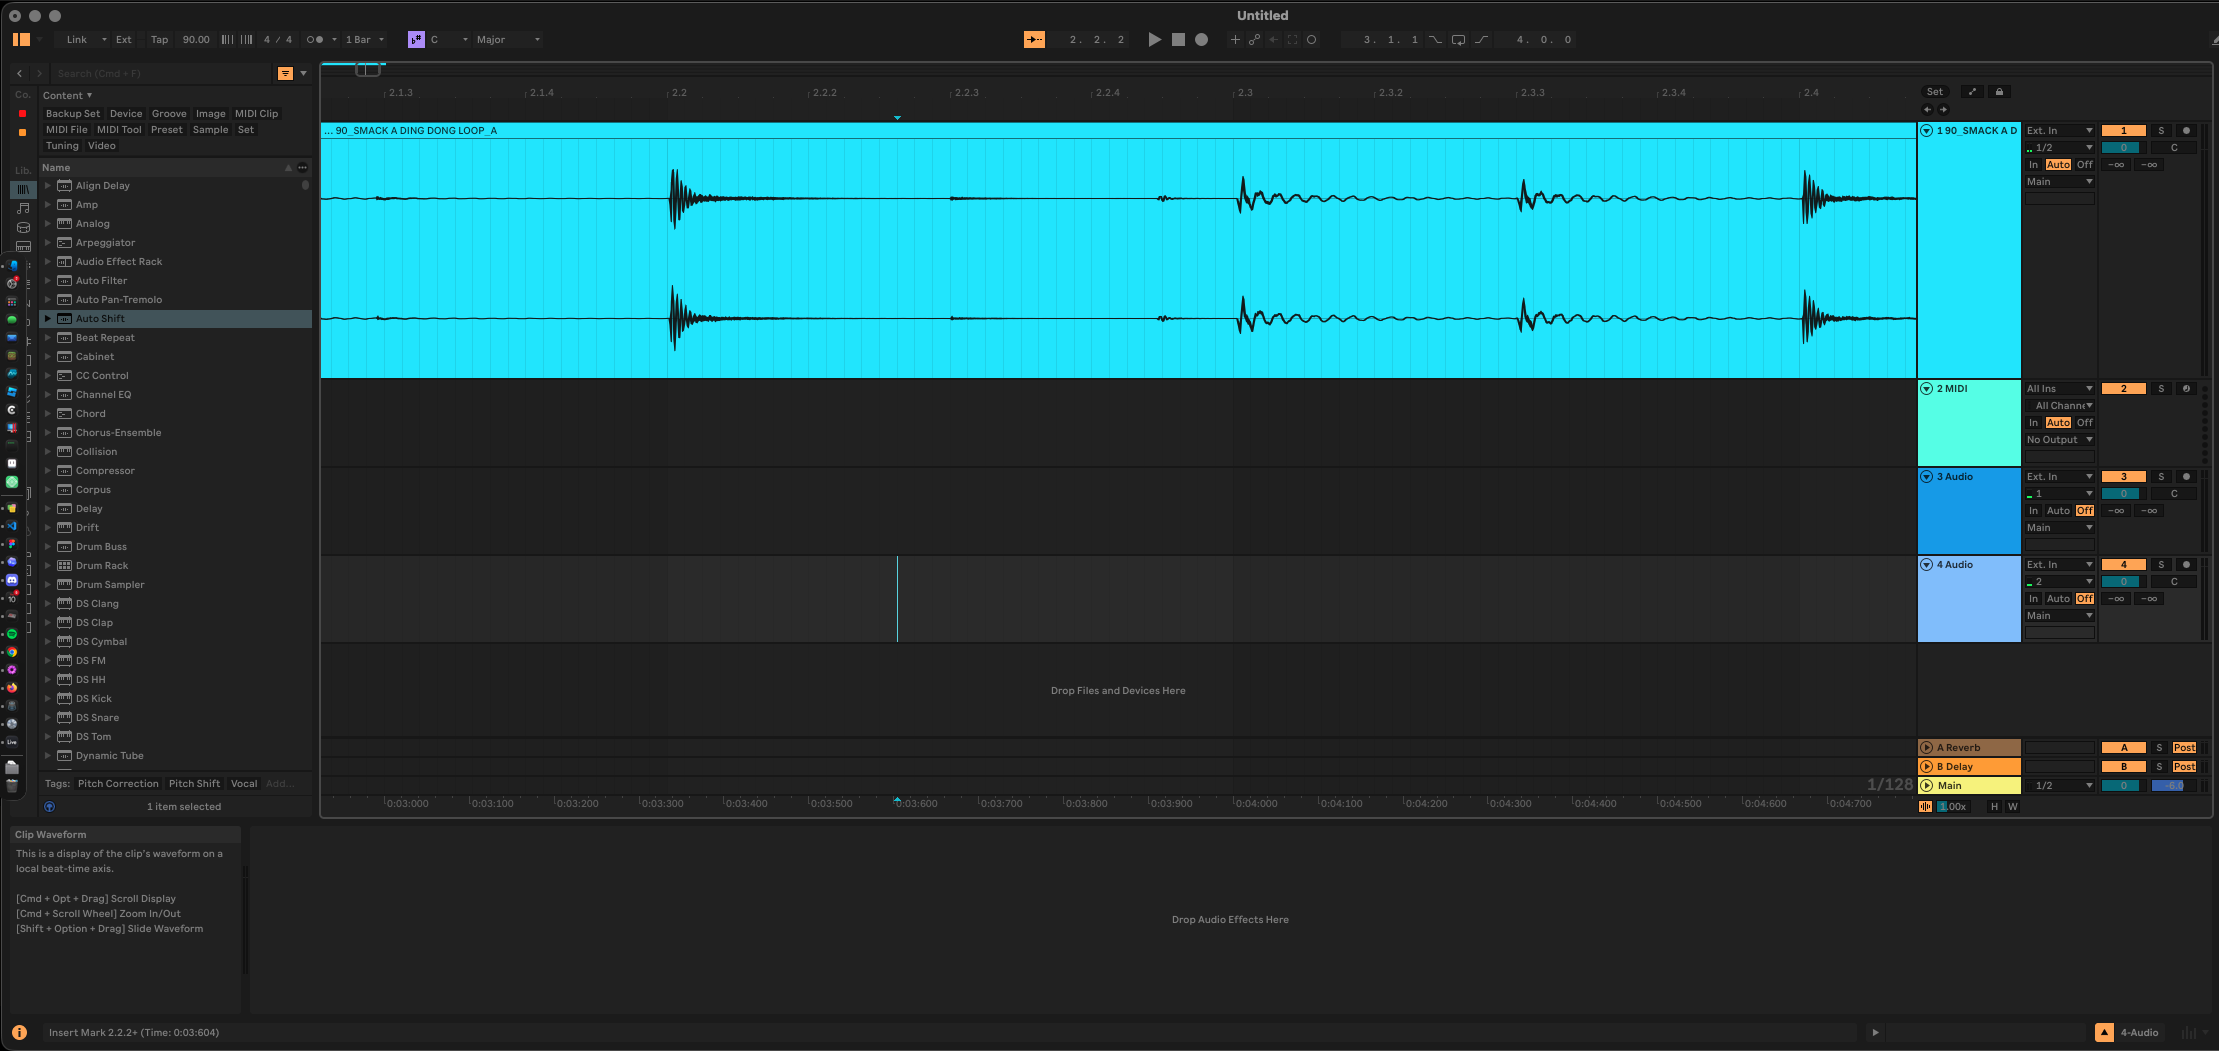
With only two days to build, we deliberately reduced a much larger set of ideas to the interactions that best communicated the concept. The resulting audio plugin could take an existing performance and either transform its tonal character or continue the performance while maintaining its microtonality and musical style. The generated audio could then move directly into Ableton Live, allowing us to mix it with other musical material as part of the demonstration.
That focus made the interface and presentation part of the product itself. Instead of asking the audience to understand the model in the abstract, we gave them a simple progression from source material, to transformation, to music they could actually hear. The result was a compact demonstration of a much larger idea, and ultimately a winning project at the Music Hackspace hackathon.
Scope for impact
A broad set of ideas was pared down to the smallest feature set that could clearly demonstrate the model within a two-day hackathon.
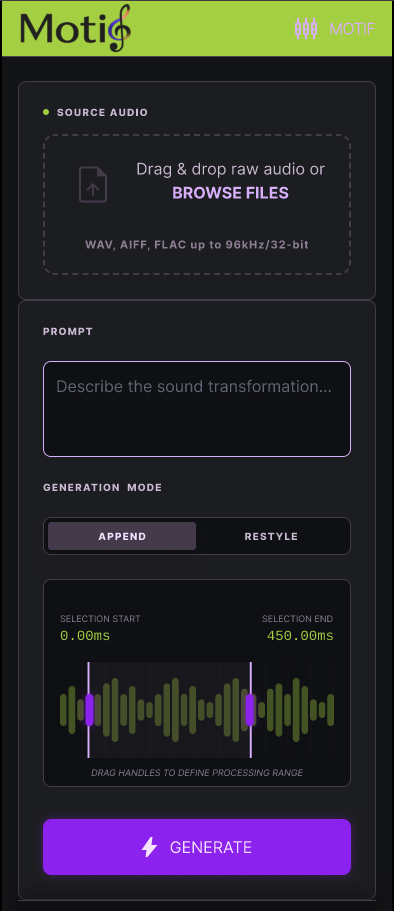
Microtonality as an experience
The plugin gave users a direct way to hear a model working with musical systems outside the dominant Western twelve-tone framework.
From model output to music
DAW integration moved generated audio directly into Ableton Live for an immediate musical demonstration.